Writing
Notes from running agent teams
Long-form write-ups of the decisions behind the numbers, with the data and the mistakes.
9 articles
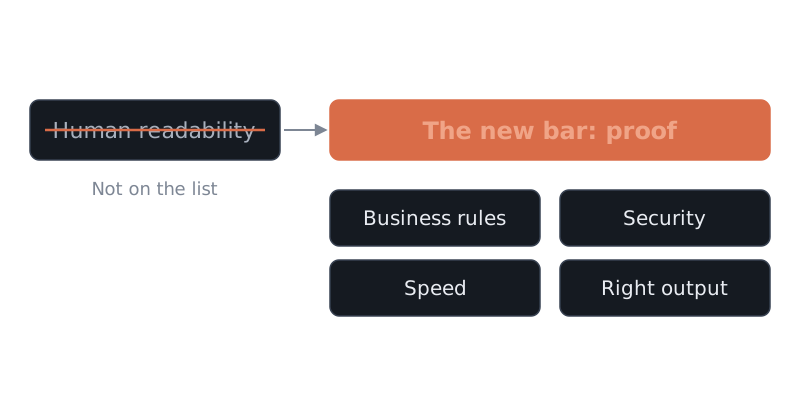
Code readability is no longer the bar
When a model reviews every change, the first question is business rules, security, speed and output, not whether a human finds the code pleasant to read.
Read the article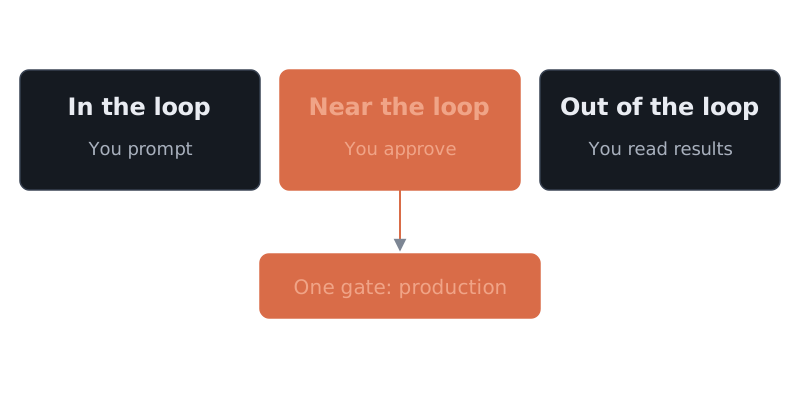
Where I still stand in an agent team
Events and clocks start the work, agents own staging, and one gate stays human: the production release.
Read the article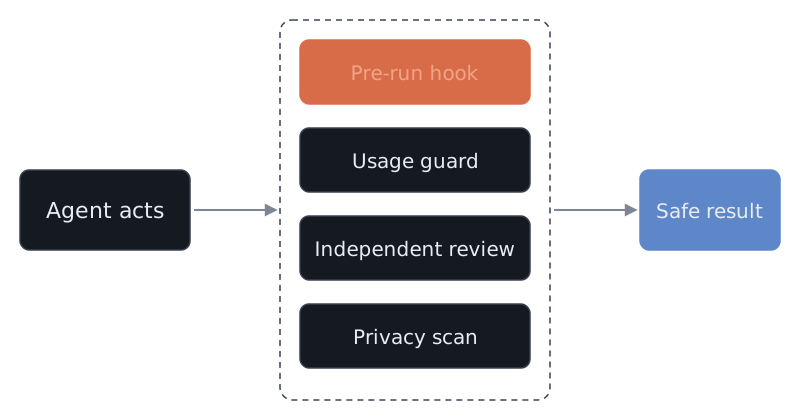
Guardrails for agents that run while I sleep
Eight guardrails that run as code, each from a real incident: pre-tool hooks, a usage guard, three-result checks and an orphan sweep.
Read the article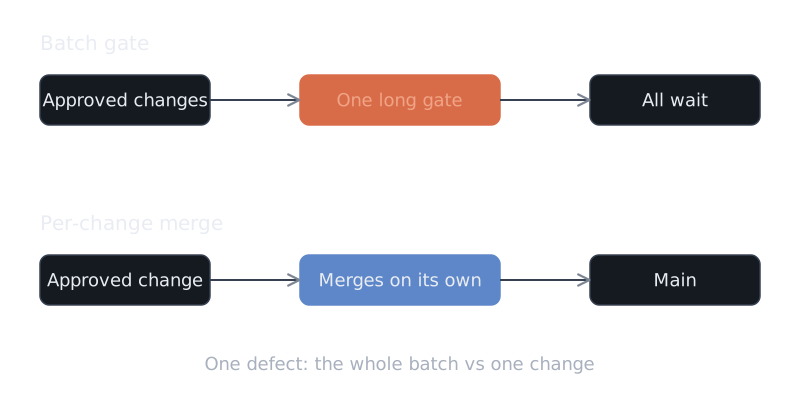
The merge train that landed 3 of 9
Why a batch merge train for an agent team failed in four days, and the per-change flow with scheduled checks that replaced it.
Read the article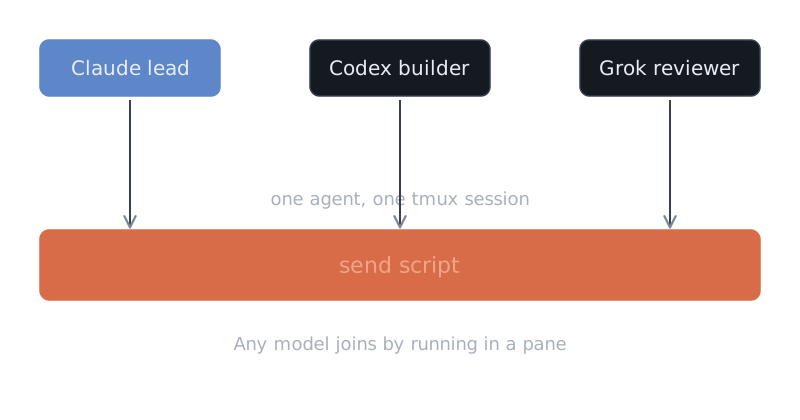
How my Claude, Codex and Grok agents talk to each other through plain tmux
One terminal message bus for agents from different vendors: how a send is verified, how agents sign their messages, and what broke.
Read the article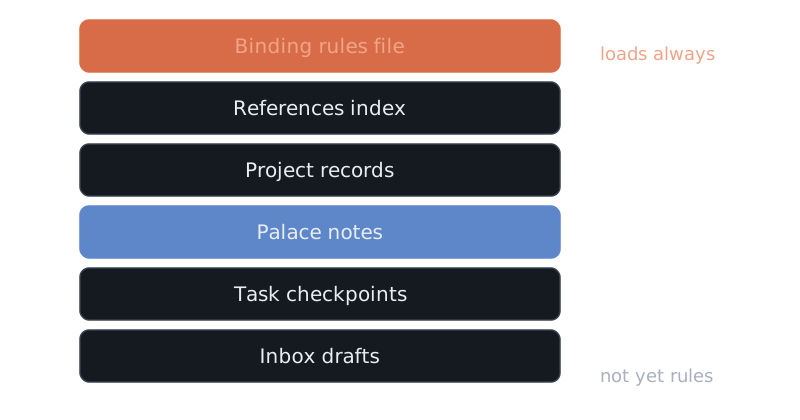
The memory palace: how fresh AI agents start with my rules
How a new or compacted agent loads the rules, the project state and its next step from plain files instead of chat history.
Read the article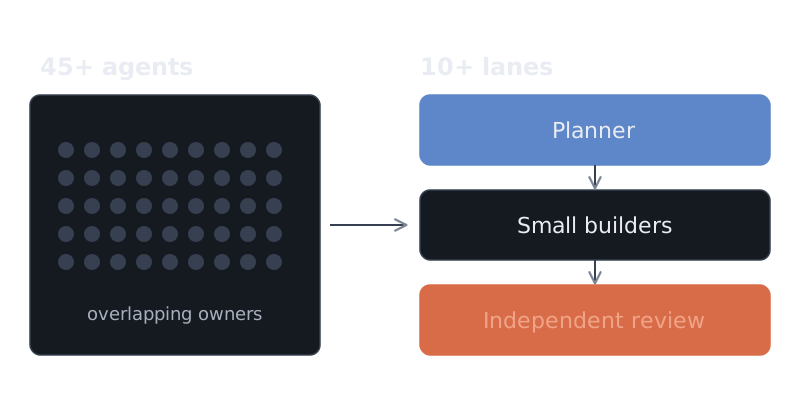
How I cut 45 AI agents to 10+ long-running lanes
Why fewer, stronger agents with clear jobs beat a crowd of helpers, and the rules that made the cut safe.
Read the article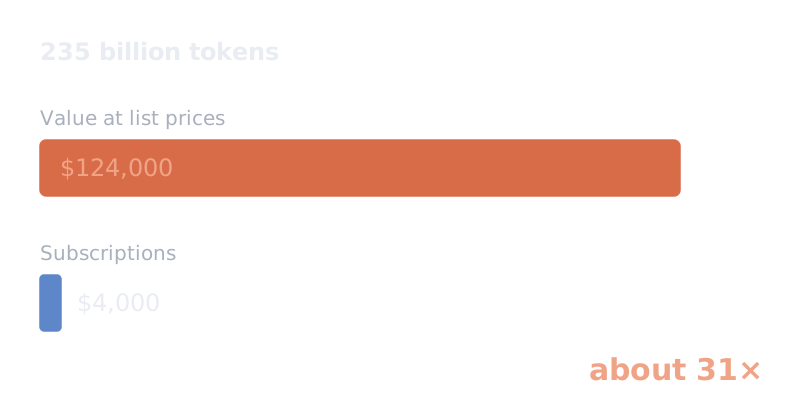
235 billion tokens of agent work: subscriptions vs metered API
How flat-rate Claude and Codex seats compared with metered API prices across 235 billion tokens, and what flat-rate plans cost in other ways.
Read the article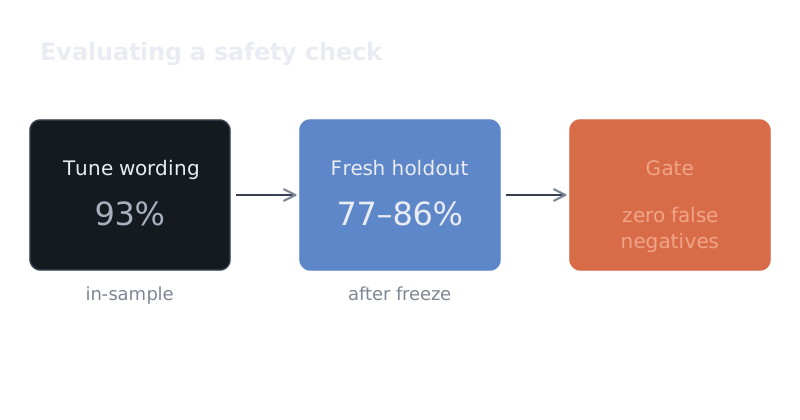
Benchmarking decision models before trusting them
How I tested a small judgment model against a frontier model, why the trivial baseline mattered, and why I retired it.
Read the article